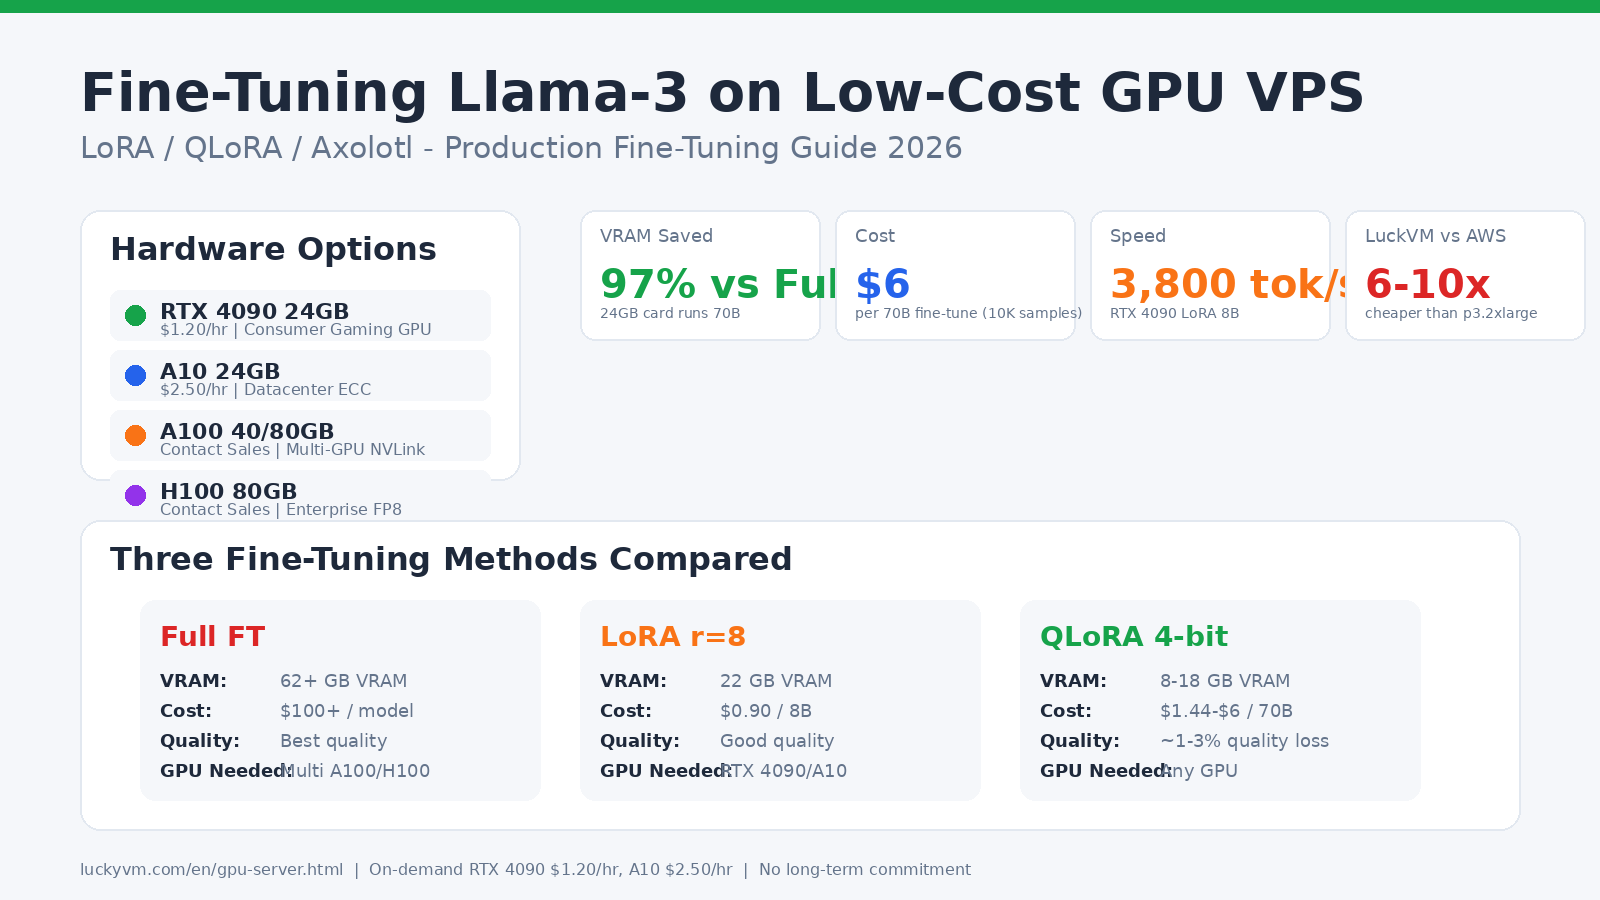
Fine-Tuning Llama-3 on Low-Cost GPU VPS 2026: LoRA, QLoRA & Axolotl on RTX 4090
TL;DR You can now fine-tune Llama-3-8B for under $1 and Llama-3-70B for about $6 using QLoRA 4-bit on a POWOKE RTX 4090 ($1.20/hr). This is 6-10x cheaper than AWS p3.
Explore articles on GPU servers and computing, including hardware configurations, deployment and workloads.
TL;DR You can now fine-tune Llama-3-8B for under $1 and Llama-3-70B for about $6 using QLoRA 4-bit on a POWOKE RTX 4090 ($1.20/hr). This is 6-10x cheaper than AWS p3.
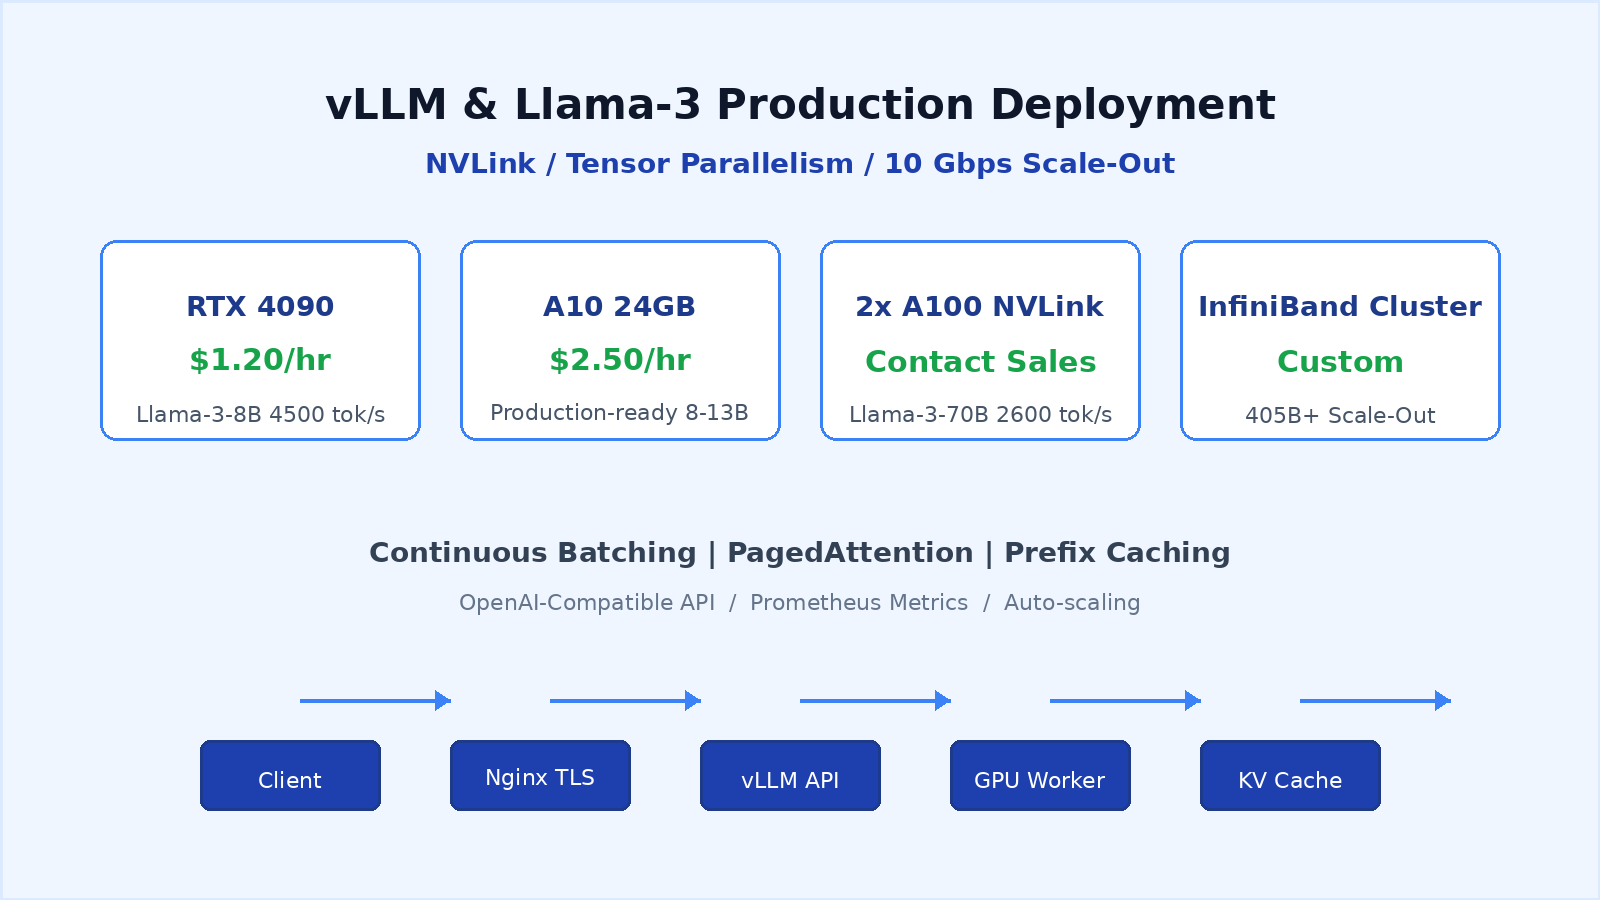
TL;DR — Skip to What You Need Side project: RTX 4090 ($1.20/hr) runs Llama-3-8B at ~4500 tok/s in vLLM Docker. Startup production: A10 24GB ($2.50/hr) with ECC VRAM, FP8 support, 10-50 RPS.
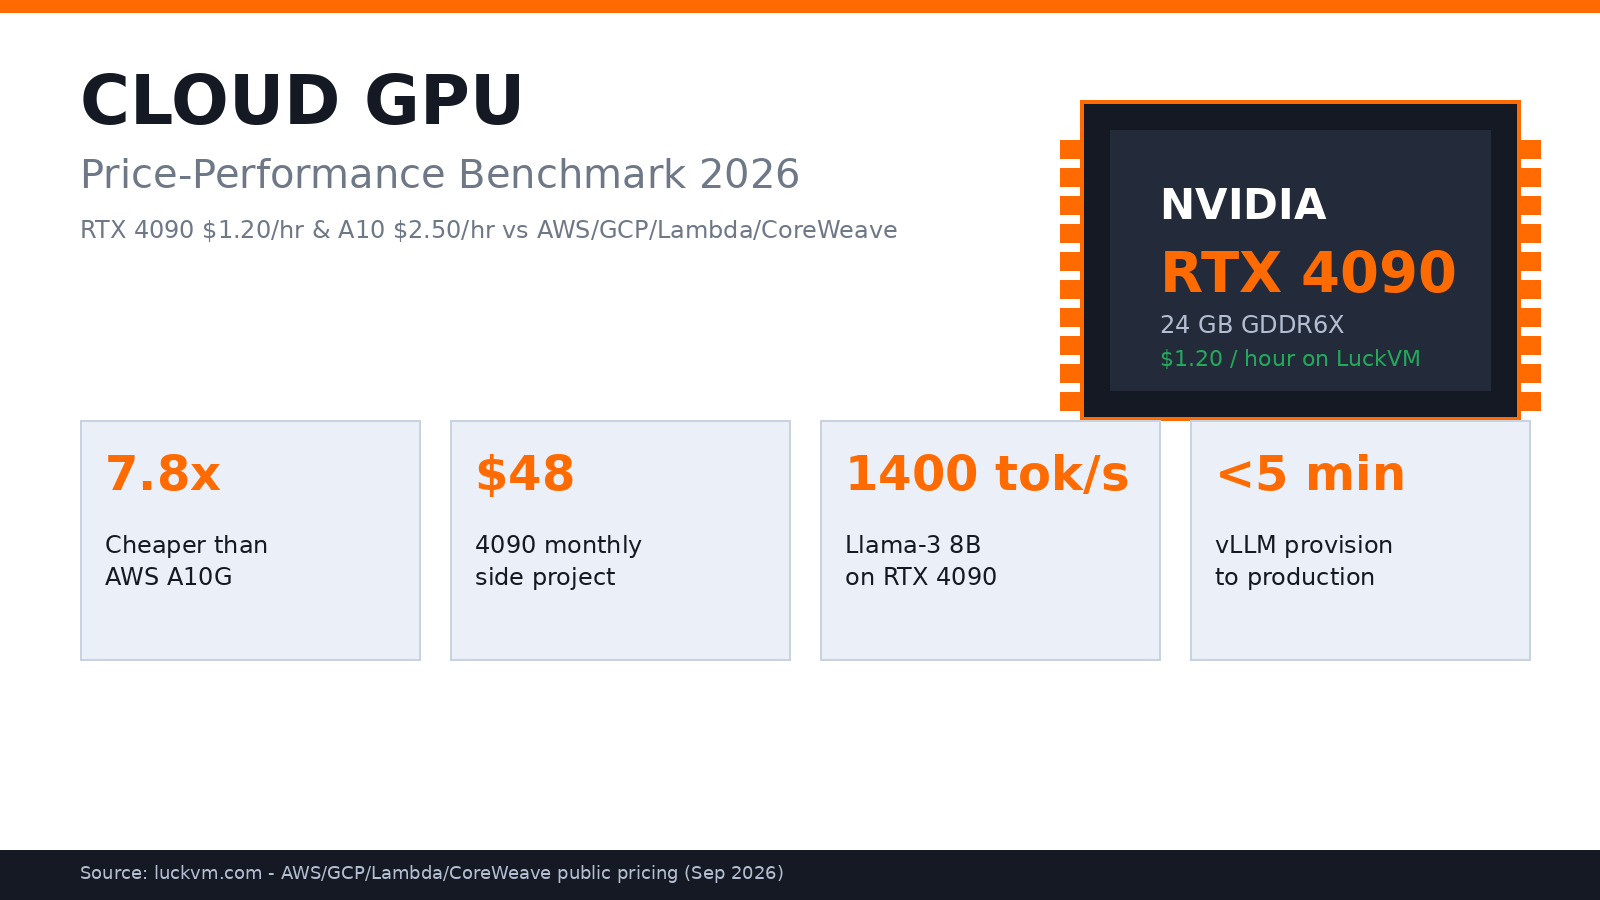
TL;DR - The Bottom Line for Busy Engineers POWOKE RTX 4090 at $1.20/hr delivers 7.8x better price-performance than AWS G5 (A10G) for LLM inference under 24GB VRAM. POWOKE A10 24GB at $2.
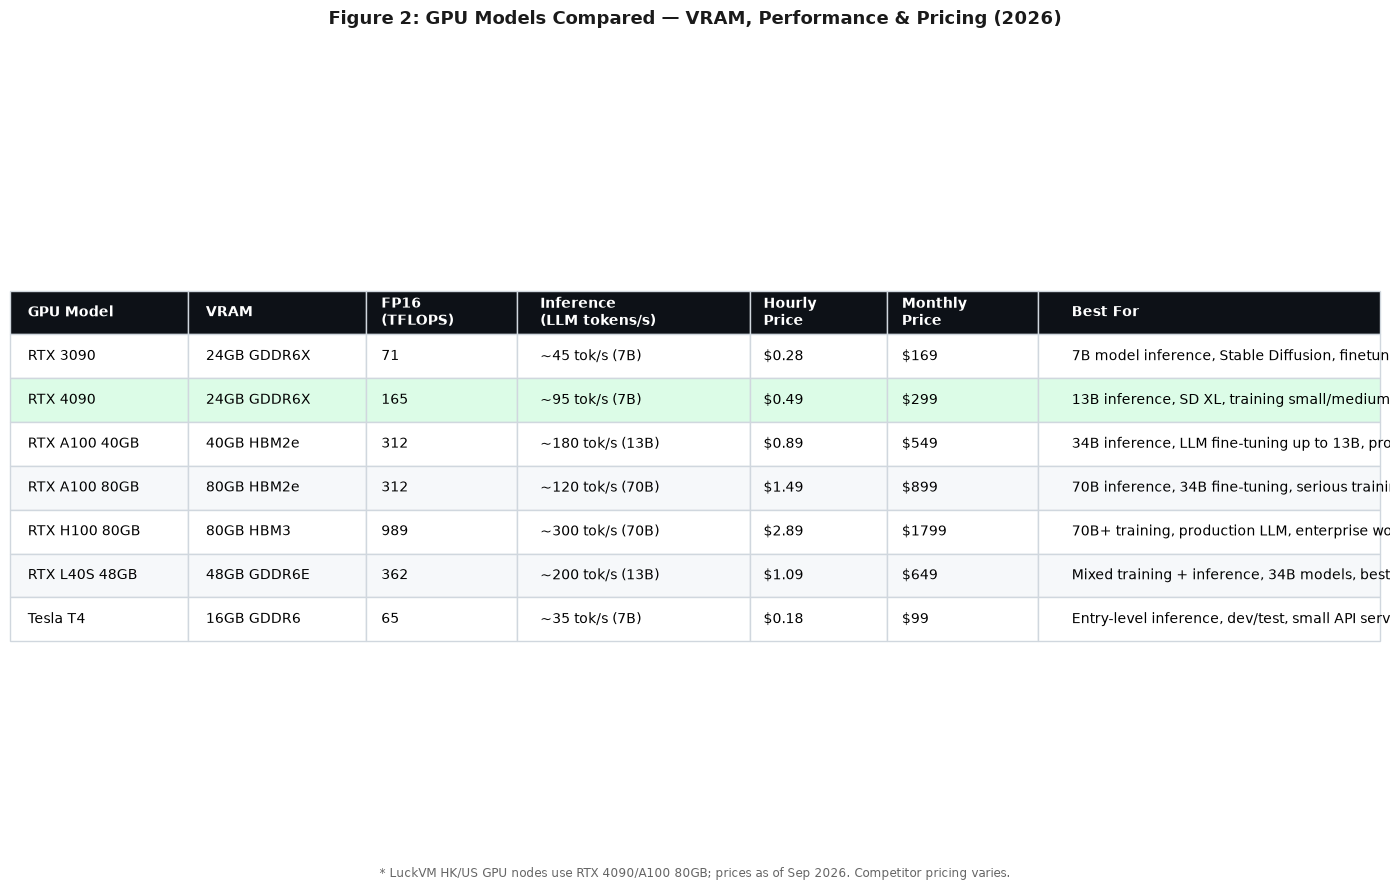
Choose GPU hosting for LLM inference, training and rendering. Compare VRAM, CPU, storage and software requirements with this POWOKE server buying guide.
Compare GPU VPS and dedicated GPU servers for machine learning. Assess memory, resource sharing and deployment requirements in this POWOKE buying guide.